Inside the Convex Engine: Building Reactive Backends Without the Friction
When you build a modern web application, you usually spend half your time syncing state between the database and the user interface, a process that frequently leads to architectural complexity and synchronization bugs. This blog post breaks down how Convex eliminates that manual labor through a reactive architecture, deterministic execution, and a unified storage layer. You will learn how the system handles real-time data flow, avoids serverless cold starts, and ensures data consistency without complex conflict resolution logic, allowing developers to focus more on business logic rather than infrastructure maintenance.
A Unified Stack for Data and Logic
Convex provides a transactional document store that combines the flexibility of JSON with relational features. Unlike traditional setups where you manage a separate database, API server, and cache, this platform integrates these components into a single environment. Your backend logic consists of queries, mutations, and actions written in TypeScript, which execute directly against the data, reducing the overhead of context switching between different tiers of the technology stack.
Unified Architecture vs. Traditional Decoupled Stacks
Component | Traditional Architecture | Convex Unified Stack |
|---|---|---|
Data Storage | Separate Database Instance (SQL/NoSQL) | Integrated Transactional Document Store |
API Layer | Standalone Server (Express/Go/Python) | Native TypeScript Queries & Mutations |
State Sync | Manual WebSocket/Polling Logic | Automatic Reactive Subscriptions |
Caching | External Cache (Redis/Memcached) | Built-in Reactive Cache |
Multi-Version Concurrency Control (MVCC)
To maintain performance during heavy traffic, the system utilizes Multi-version Concurrency Control (MVCC) to provide snapshot isolation. This architecture allows the database to provide a consistent view of the data. When you run a query, you see a consistent version of the data from the moment the query began, even if other users are writing to the database simultaneously. This prevents partial data reads and ensures that your UI remains stable, which is critical for maintaining a high-quality user experience during concurrent data updates.
The Reactive Engine and Subscription Logic
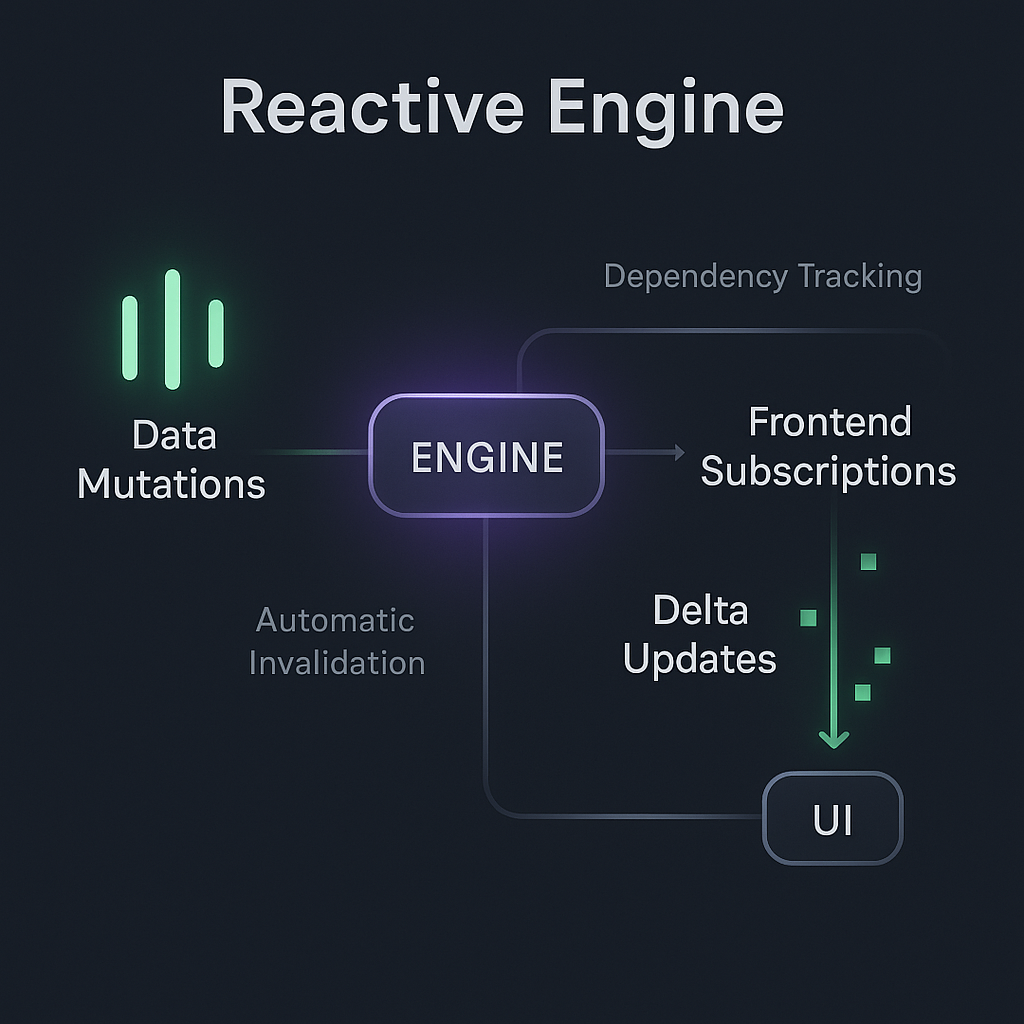
The core of the platform is a reactive engine that transforms the database from a passive storage bin into an active participant in the application lifecycle. Instead of your frontend asking "is there new data?", the backend notifies the frontend when relevant changes occur, following the principles of reactive programming where data streams propagate changes automatically.
Dependency Tracking: Convex tracks a query's database reads, which can include scanned index ranges as well as individual documents.
Automatic Invalidation: When a write overlaps a subscribed query's read set, Convex can rerun the query and refresh its result.
Reactive Result Updates: Convex pushes new query results to subscribed clients. Do not assume every update is transmitted only as a delta rather than a refreshed result.
This model removes the requirement for complex state management libraries that often clutter frontend codebases.
Function Runtimes and Startup Latency
Convex's default JavaScript runtime runs compatible functions in V8 isolates, avoiding a conventional container startup for each request. This does not describe every Convex function: actions that need Node.js-specific functionality use a separate runtime. Compare startup behavior for the function type your application actually uses.
Convex describes its default runtime as having no cold starts, though creating an isolate when one cannot be reused can still add latency. Its engineering article compares about 10 ms to start a V8 isolate with 500 ms–10 s to start an AWS Lambda instance. These are published startup comparisons, not guarantees that every application function completes instantly or has a particular end-to-end latency.
Determinism, Debugging, and Recovery
Convex requires queries and mutations to behave deterministically so the system can retry them when necessary, including after transaction conflicts. That does not by itself give developers a documented way to replay a particular past production execution or query arbitrary historical document states. For debugging, use function logs; for recorded events, consider audit logging; and for recovery, evaluate available backups. Restoring a backup replaces the deployment's existing data.
Automatic Retries: Deterministic queries and mutations can be retried by Convex; this is different from a developer replaying a saved execution to reproduce an error.
Audit Logs: Functions can emit audit logs for events you choose to record. This is not an automatic reconstruction of every past database state.
Point-in-Time Recovery: An available backup provides a recovery option, but restoring it replaces existing deployment data; MVCC alone should not be presented as an arbitrary historical-query or deletion-recovery interface.
Advanced Query Optimization and Backpressure
To keep the system responsive for millions of users, the platform employs advanced query optimization techniques. One such method is predicate pushdown, which moves filtering logic closer to the data source. This process ensures that only the data that matches your criteria is ever read from disk, drastically reducing I/O overhead and improving execution speed for large datasets.
When a client cannot keep up with the volume of updates being sent from the server, the system triggers backpressure handling. This mechanism manages the flow of data by:
Buffering updates on the server until the client is ready to process them.
Throttling the sync rate to prevent the client's browser from freezing due to message saturation.
Reconciling the state once the connection stabilizes to ensure the client reflects the most recent database version.
Security and Multi-Tenant Isolation
In a multi-tenant application, keeping one customer's data away from another is vital for privacy. Convex supports authentication, but identifying a signed-in user does not automatically authorize access to a tenant's data. Check identity and tenant membership in public queries and mutations before reading or changing customer records, including data returned by subscribed queries.
Deployment Boundaries: A project has one shared production deployment by default; Convex does not automatically place each customer's subscriptions and functions in a separate deployment. Query concurrency limits are defined at the deployment level, so do not assume that one tenant's workload cannot affect another. Configure separate deployments deliberately if the application requires them.
The Future of Real-Time Development
Moving away from the traditional request-response cycle simplifies your development workflow and reduces the cognitive load of managing distributed state. You no longer have to worry about cache invalidation or manually updating the UI when data changes on the server. By merging the database, serverless functions, and a reactive sync engine into one coherent system, you can focus on building features rather than managing infrastructure. This architectural shift ensures that your application remains fast, consistent, and scalable as your user base grows, providing a foundation for the next generation of interactive web experiences.